The Modern Landscape of the Web
How the internet went from a network of knowledge to an ecosystem dominated by visibility, engagement, and the race for attention.
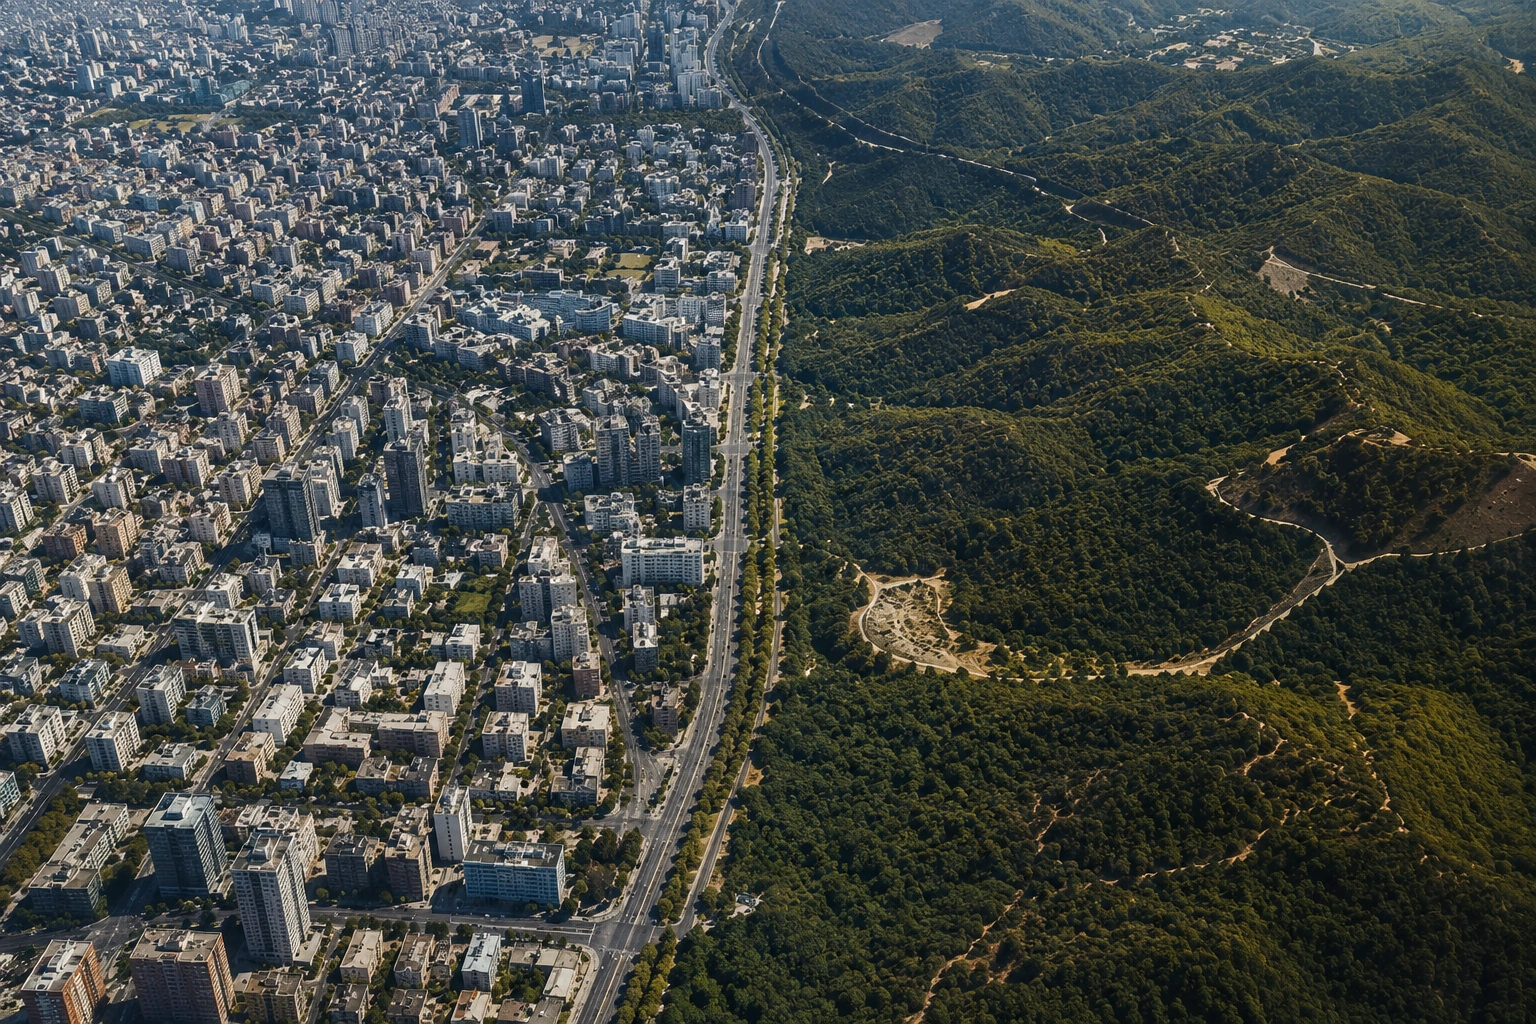
FIG 1.0 - Urbanization transforms landscapes to the point of making them unrecognizable.
The past few years have profoundly transformed the internet. New approaches, technologies, and trends have gradually reshaped its functioning and priorities. Today, the internet is very different from what it was in its early days: its objectives have moved away from a human-centered vision.
Related Insights
A multimodal Knowledge Platform
The Internet isn't dead, it changed.
The Paradox of the Front-End Ecosystem
Tensegrity Team
Internet | Algorithms | Discovery
Tensegrity publishes content on artificial intelligence, machine learning, data systems, and modern software development. The team consists of engineers and consultants who design intelligent technologies and deploy them into production to solve real-world problems.
T he internet has become one of the most powerful information systems ever created, yet its structure is increasingly at odds with the original vision that popularized it. What began as a network for the exchange of knowledge has evolved into an environment dominated by visibility algorithms, fragmented content streams, and engagement-driven platforms. Information is now produced at a scale far beyond the capacity of any individual to meaningfully process it, and as the volume of content continues to accelerate, the ability to locate reliable, contextual, and coherent knowledge becomes increasingly blurred.
Modern search systems were designed to solve the problem of scale, but in doing so they gradually shifted the internet away from a semantic based research and toward heuristic ranking. Earlier discovery systems relied primarily on direct relevance through keywords, metadata, and textual relationships. Today, visibility is often determined through engagement metrics, popularity signals, behavioral prediction, backlink density, and platform optimization strategies. These systems are highly efficient at surfacing content that performs well algorithmically, but they are not necessarily designed to preserve depth, continuity, or intellectual clarity.
From the Early Web to the Modern Web
The evolution of the internet is not solely about technology. It also reflects a gradual shift in the way information is organized, discovered, and consumed.
Tab 1 — Structural evolution of information discovery and organization mechanisms on the Web.
As a result, users are frequently exposed to overwhelming volumes of fragmented information. Valuable sources may remain buried beneath highly optimized but contextually shallow material. Searches intended to answer straightforward questions can quickly devolve into endless navigation through advertisements, duplicated articles, recommendation systems, and recycled content. In many cases, the issue is no longer access to information, but rather the absence of meaningful structure surrounding it.
Observation The amount of available information is increasing faster than the human capacity to process it. The challenge therefore becomes organizational rather than informational.
This fragmentation extends beyond search itself. The modern web increasingly prioritizes immediacy, virality, and high-frequency consumption. Platforms compete for attention within an economy optimized around retention and engagement, encouraging increasingly rapid forms of interaction that leave little room for deliberate exploration or sustained comprehension. The consequence is an environment where information exists everywhere, yet understanding becomes progressively more difficult to achieve.
The rise of machine-generated content
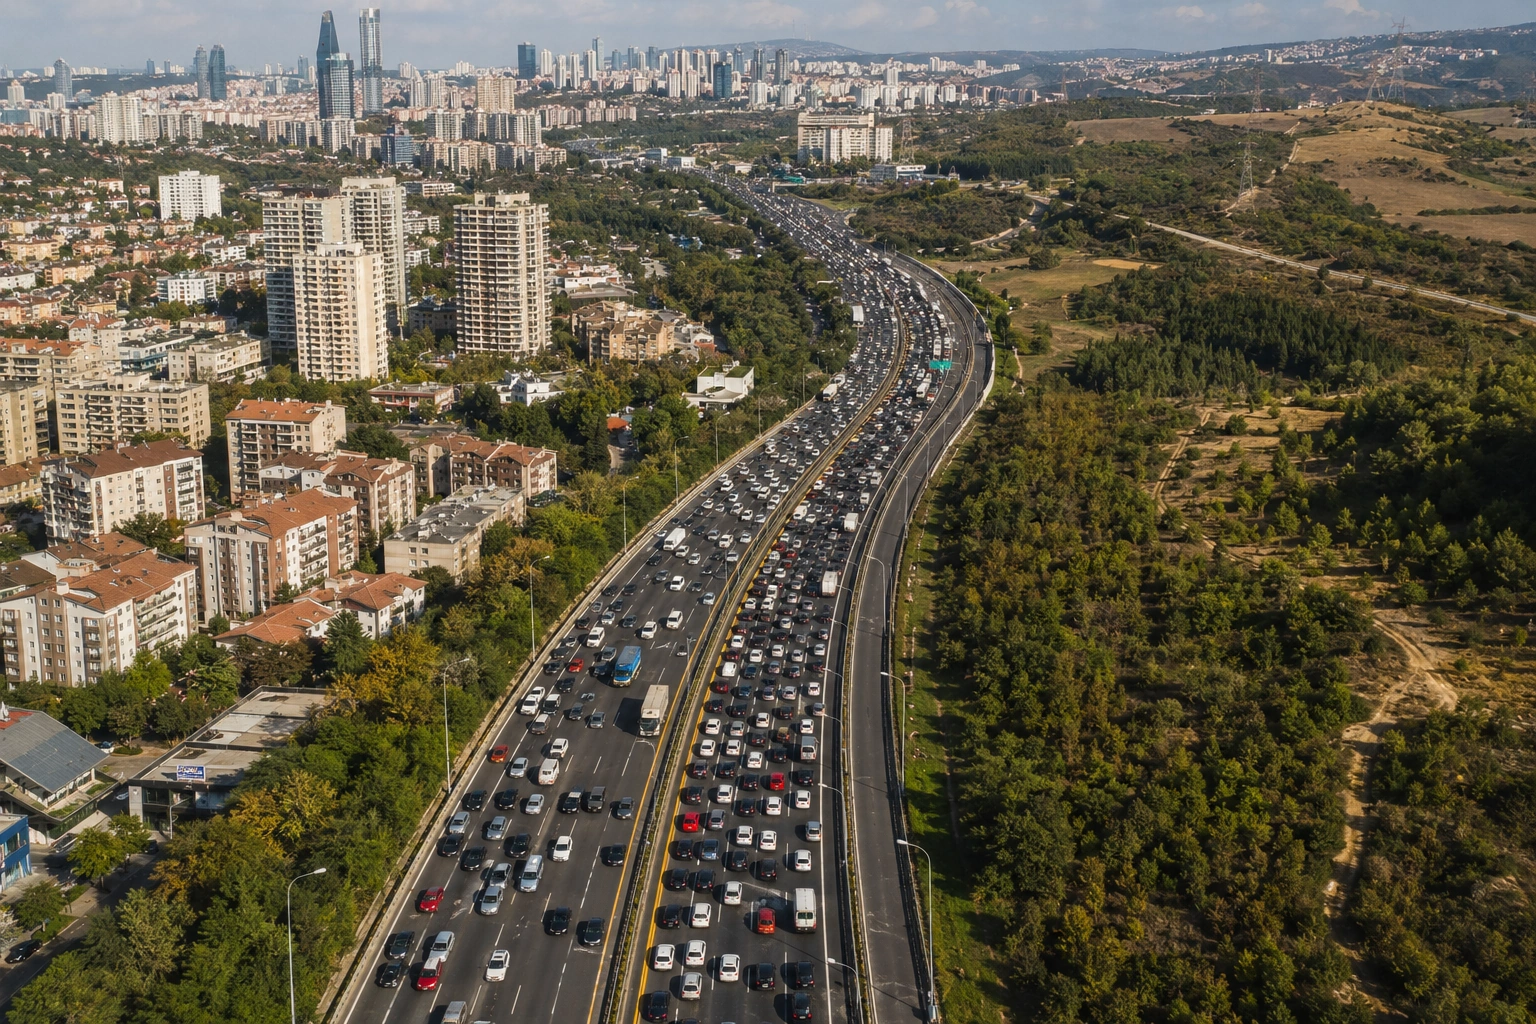
FIG 3 - A dense Traffic
Internet traffic far exceeds what we can realistically explore. The challenge is no longer simply accessing information, but finding clear paths through an ever-growing amount of content.
At the same time, the rise of large-scale machine-generated content introduces an additional layer of complexity. Automated systems are now capable of producing enormous quantities of text, media, and synthetic engagement at a speed impossible for human ecosystems to match. While artificial intelligence represents a major technological advancement, the surrounding infrastructure for contextual verification, attribution, and semantic integrity remains immature. Increasingly, users encounter information detached from identifiable expertise, authorship, or traceable knowledge chains. The web risks becoming not only noisy, but structurally ambiguous.
Critical point Automatic generation is advancing faster than verification, attribution, and traceability mechanisms.
The core problem is therefore not simply one of scale, but one of architecture. The internet was largely built around isolated pages competing for visibility within massive indexing systems. Knowledge exists, but it is scattered, disconnected, and often stripped of meaningful relational context. Modern platforms excel at distributing information rapidly, yet they struggle to preserve coherence across domains, sources, and layers of understanding.
All of these dynamics combined increasingly leave both users and creators navigating an environment that feels fragmented, saturated, and difficult to meaningfully engage with. For the ordinary user searching for information, the modern web often becomes less about discovering knowledge and more about filtering overwhelming volumes of competing content. At the same time, creators and writers are placed under growing pressure to adapt their work to visibility systems largely governed by optimization strategies, platform incentives, and algorithmic discoverability.
The gradual disappearance of the specialized Web
In the earlier stages of the internet, it was common to encounter smaller, highly specialized websites dedicated to a single topic, community, or field of interest. These spaces were often limited in scale, but they provided focused environments where information remained closely tied to its subject matter. Today, much of the web has consolidated around large platforms and centralized networks capable of amplifying visibility through recommendation systems and search dominance. As a consequence, independent creators increasingly depend on existing ecosystems to reach audiences, requiring them to optimize content not only for readers, but also for algorithms, indexing systems, and engagement metrics.
-
Specialized sites
-
Community Forum
-
Independent Blogs
-
Personal Documentation
This shift also changes the experience of information discovery itself. Users searching for a specific topic frequently encounter environments designed to maximize retention rather than deepen understanding. For example, someone searching for a particular product may successfully arrive at an online store that provides the requested item, yet the surrounding interface is often structured primarily around behavioral recommendations, engagement pathways, and internal performance metrics. Instead of encouraging a deeper exploration of the subject itself, these systems tend to redirect attention toward adjacent content, additional products, or algorithmically selected suggestions intended to prolong interaction.
Over time, this creates an informational environment characterized by constant interruption. Content is delivered rapidly, densely, and in highly fragmented forms, reducing the likelihood that sustained attention will remain focused on a single subject for extended periods. Rather than encouraging deeper exploration, many modern systems incentivize continuous movement between loosely connected streams of information.
Focus, Learning, and Understanding
Concerns surrounding the cognitive effects of this model have increasingly become the subject of broader discussion and research. While the relationship between digital media and attention remains complex and not fully understood, there is growing evidence suggesting that environments built around frequent interruptions, rapid context switching, and high-intensity information exposure can negatively affect concentration, working memory, and long-term retention for certain users and usage patterns. Importantly, the issue is not the availability of information itself, but the structure through which it is consumed.
"Meaningful understanding generally emerges from sustained contextual reinforcement rather than isolated exposures to information."
Meaningful learning generally requires repeated engagement, contextual reinforcement, active effort, and time spent focusing on a subject deeply enough to build durable cognitive associations. Passive exposure to large volumes of rapidly changing content does not necessarily translate into understanding or memory retention. In many cases, comprehension develops not through speed, but through deliberate engagement, reflection, repetition, and the process of navigating complexity over time.
Interestingly, this principle also appears in machine learning systems themselves. Large language models do not develop coherent semantic relationships from isolated exposure to information. Instead, they require repeated training across vast quantities of related and contextually overlapping data in order to model associations effectively. Human learning is obviously far more complex than statistical training systems, but the comparison illustrates an important principle: meaningful understanding generally emerges through sustained contextual reinforcement rather than isolated bursts of information exposure.
The modern web excels at distributing information quickly, but speed alone does not guarantee comprehension. As digital environments become increasingly optimized for immediacy and engagement, there is a growing need for systems designed around slower, more structured, and more intentional forms of interaction with knowledge.
Toward a New Knowledge Architecture
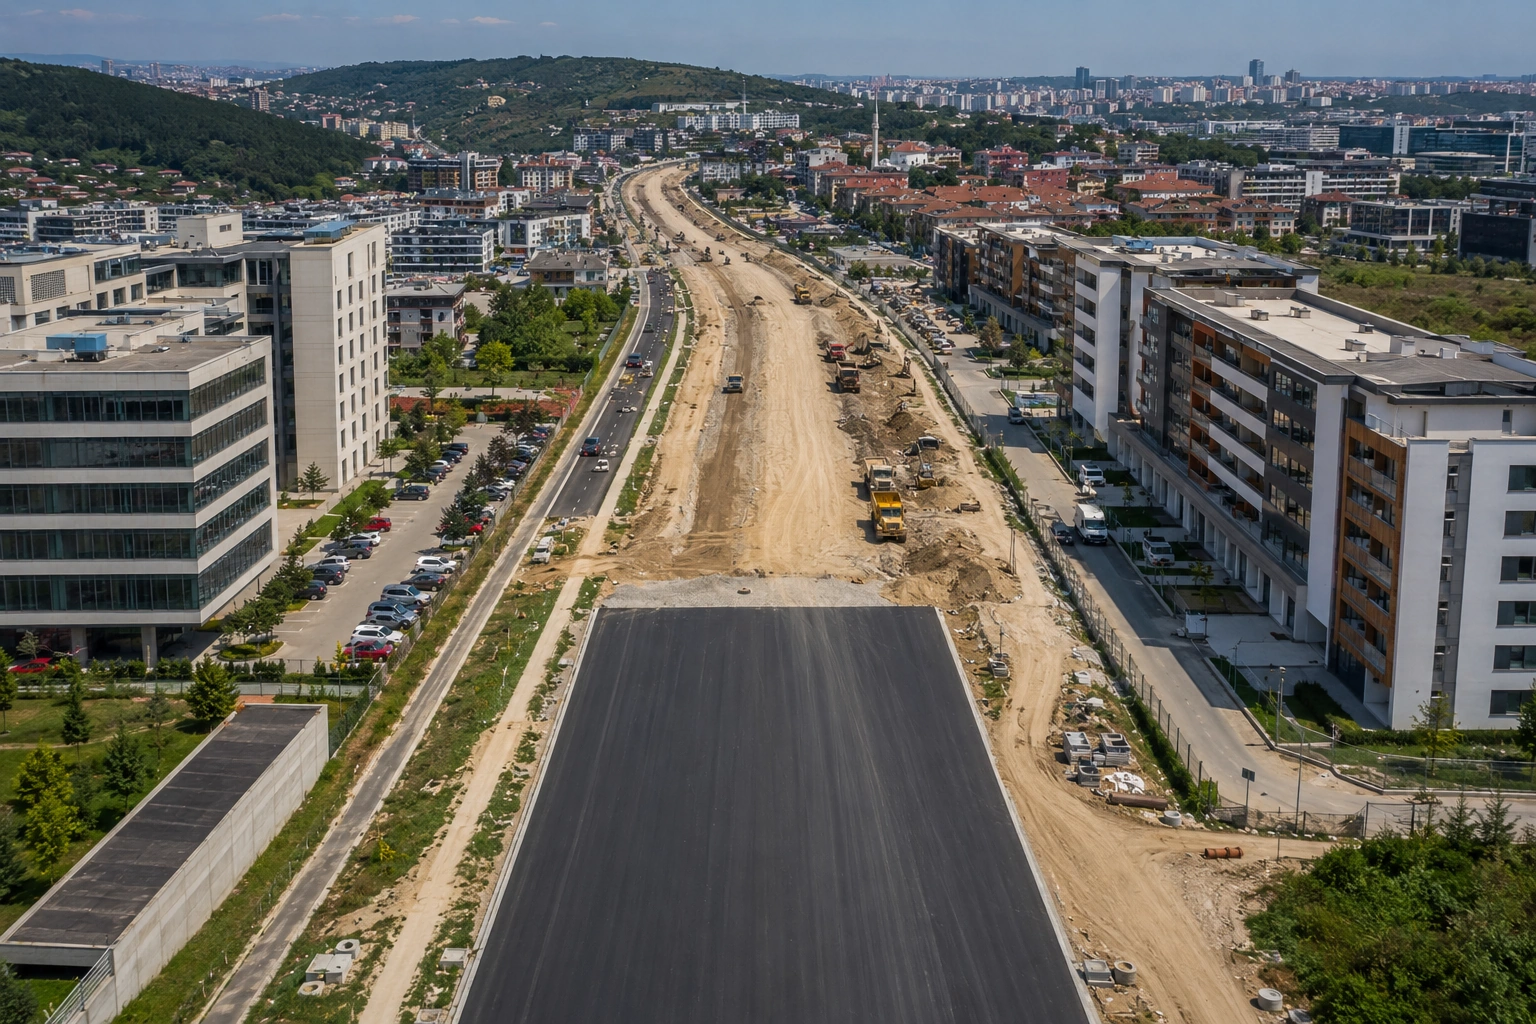
FIG 3 - Building a new road
It is not simply about responding to growing demand, but about building alternatives that are closer to communities: new platforms for searching, connecting, and organizing knowledge.
Ultimately, the trajectory the modern internet is following may become increasingly unsustainable as a meaningful platform for knowledge discovery and long-term intellectual engagement. While information has never been more abundant, the surrounding environment often feels fragmented, incoherent, and only loosely connected. The web still contains remarkable work, scientific research, thoughtful essays, technical documentation, long-form analysis, and deeply specialized communities, yet the systems responsible for surfacing and organizing this information struggle to preserve contextual coherence at scale.
Fondamental Question:
How do we build systems that prioritize coherence and context rather than visibility alone?
As a result, genuinely valuable contributions can easily become overshadowed by content optimized primarily for visibility, engagement, or algorithmic performance. The work of dedicated individuals and specialized communities may exist in extraordinary depth yet remain difficult to discover beneath increasingly dense layers of recommendation systems, trend cycles, and fragmented information streams.
The challenge facing the future web is therefore not simply one of access, but one of structure. Information systems capable of understanding semantic relationships, preserving contextual links between ideas, and emphasizing meaningful discovery over pure visibility metrics may become increasingly necessary. Equally important is the existence of curated environments where information can remain organized, interconnected, and navigable without being constantly diluted by noise and volatility.
The next evolution of the internet may depend not on producing more information, but on building systems capable of preserving coherence, depth, and meaningful connection across the knowledge that already exists.